Comparison
GPT-6 Astra vs Claude Fable 5.1: benchmarks and cost
Compare GPT-6 Astra and Claude Fable 5.1 with published benchmarks, Agent Arena confidence intervals, API prices and two explicit cache scenarios.
GPT-6 Astra leads the cited Artificial Analysis coding tests, while Claude Fable 5.1 scores higher on AA-Briefcase. Their Agent Arena intervals overlap. On API Stock, Astra costs less for the uncached workload below; Fable costs less if 95% of its input is actually billed as cache reads. Choose by task and measured usage.
What do the published benchmarks show?
Artificial Analysis provides the results below, retrieved 5 November 2026. The configurations are GPT-6 Astra: Max and Claude Fable 5.1: Max, Default Fallback. The fallback label belongs to the evaluated configuration; do not assume our API reproduces it.
| Metric and unit | GPT-6 Astra | Claude Fable 5.1 |
|---|---|---|
| Intelligence Index v5.0.1 · points | 57 | 49 |
| Terminal-Bench 4.0 · % | 59 | 52 |
| FrontierCode 2.0 · % | 42 | 32 |
| AA-Briefcase v1.1 · Elo | 1569 | 1669 |
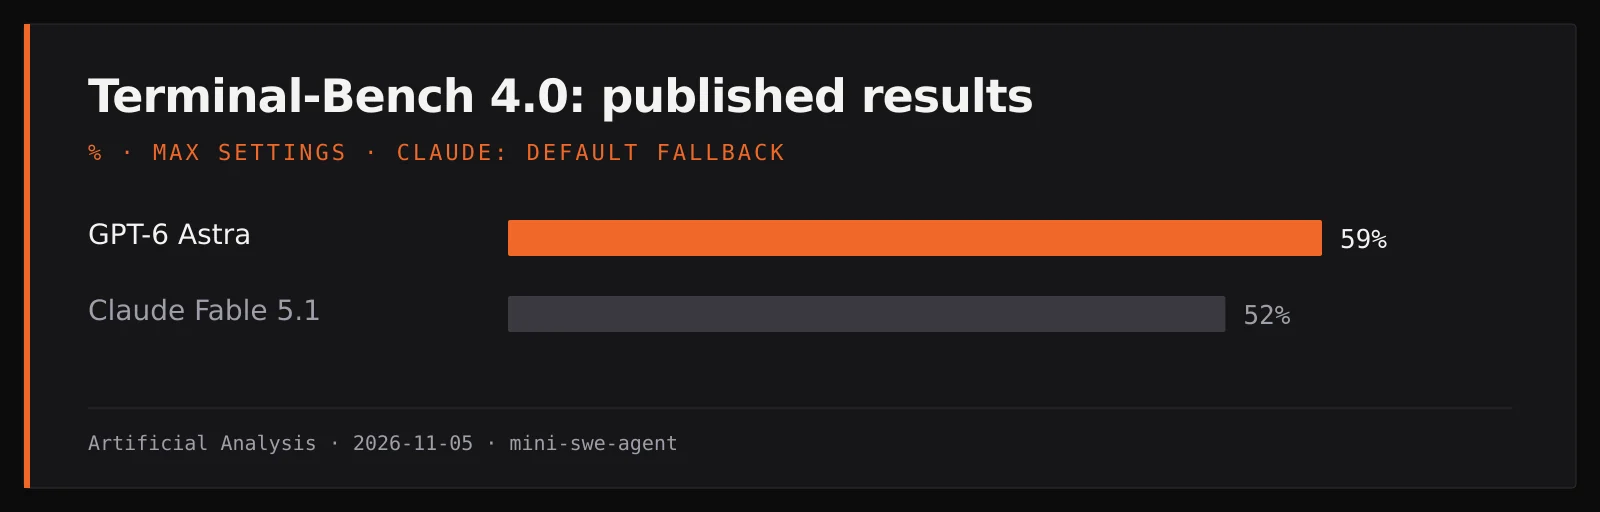
Terminal-Bench 4.0 runs 66 terminal tasks through mini-swe-agent, averaging pass@1 over three repeats; all verifier tests must pass. FrontierCode 2.0 uses 132 tasks, three attempts and Stirrup, with held-out tests and an LLM-judged rubric. Their percentages describe different tasks and scoring rules.
Intelligence Index v5.0.1 combines nine evaluations: index points are not percentage accuracy. Max is each model's maximum effort setting, not an equal compute budget. We preserve the source's displayed precision. The comparison page does not supply row-level confidence intervals or exact run timestamps; the date above is our retrieval date.
AA-Briefcase v1.1 evaluates 91 tasks producing work files; its combined Elo includes rubric, analytical quality and presentation. It is not a percentage of successful code fixes.
Astra leads these coding evaluations and the aggregate index; Fable leads AA-Briefcase, whose scale is Elo. Start a coding-agent trial with Astra and include Fable when the acceptance criteria concern office documents. The task mix changes what a useful lead means.
What does Agent Arena add?
The Agent Arena leaderboard dated 4 November 2026 offers a separate view of real sessions:
| Model | Net Improvement, percentage points · estimate ± 95% CI half-width | Sessions |
|---|---|---|
| GPT-6 Astra (Max) | 14.70 ± 2.07 | 15,475 |
| Claude Fable 5.1 (Max) | 13.86 ± 1.87 | 17,518 |
Arena's method estimates model-selection effects from session signals using randomized components. Net Improvement is a treatment-effect estimate, not a task-completion rate. It cannot be combined with Terminal-Bench percentages.
Astra and Fable have overlapping intervals: 14.70 versus 13.86 percentage points alone does not establish a clear winner. These are external evaluations, not measurements of API Stock or its routing. The dated evidence snapshot preserves the numbers and conditions.
How does cache change the token budget?
The catalog, retrieved 5 November 2026, lists these API Stock USD per million tokens. They are service tariffs, not the costs reported by Artificial Analysis or Arena.
| Token category | GPT-6 Astra | Claude Fable 5.1 |
|---|---|---|
| Uncached input | $8.00 | $10.00 |
| Output | $40.00 | $50.00 |
| Cache read | $0.80 | $0.25 |
| Cache write | $10.00 | $12.50 |
Assume 100,000 total input tokens and 1,000 billed output tokens per request:
| Conditional workload | Astra | Fable |
|---|---|---|
| All 100K input uncached | $0.84 | $1.05 |
| 95K cache reads + 5K uncached input; no cache writes | $0.156 | $0.12375 |
For the second row, Astra is 0.095 × 0.80 + 0.005 × 8 + 0.001 × 40; Fable is 0.095 × 0.25 + 0.005 × 10 + 0.001 × 50. The cache-read and uncached counts partition the same 100K input; cached tokens are not added twice.
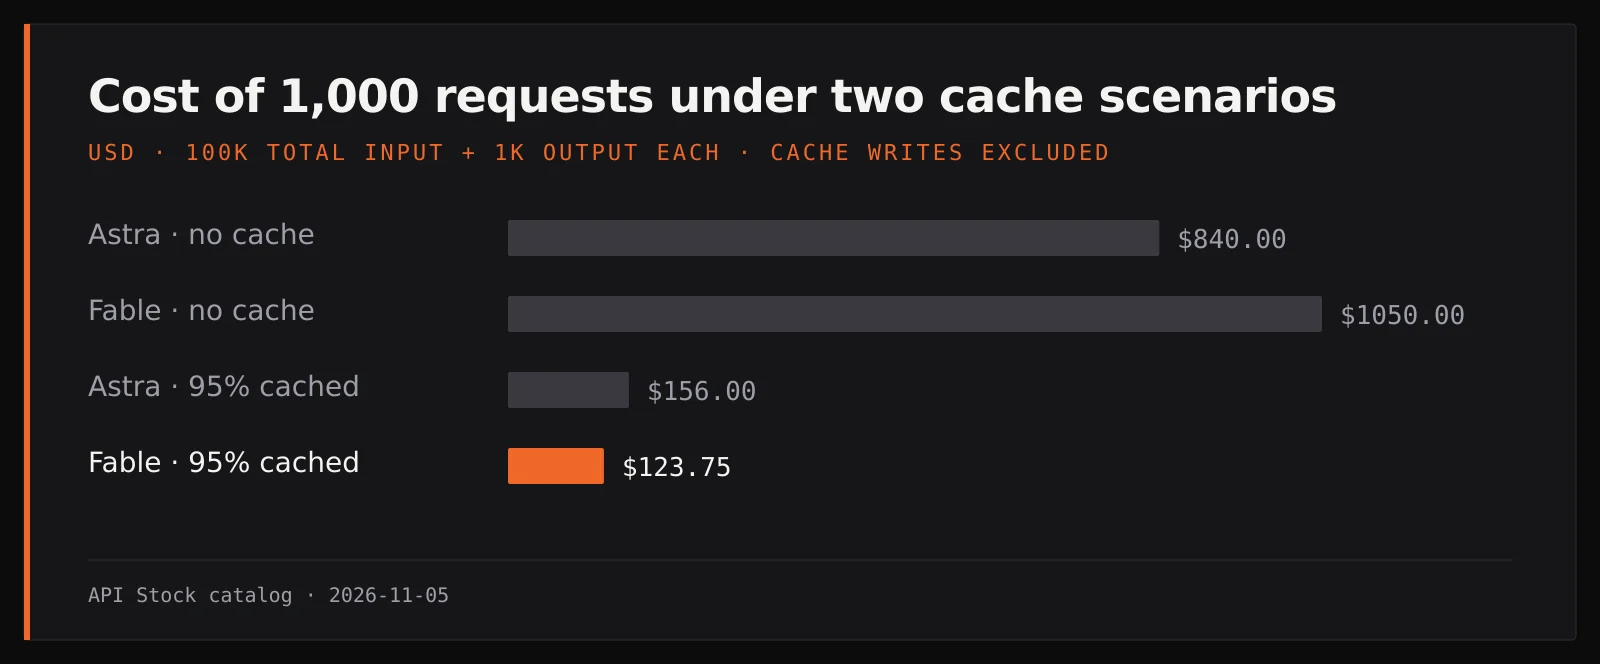
For one thousand requests, the uncached totals are $840 and $1,050. With 95% input cache reads on every request, excluding writes, they become $156 and $123.75. This is a conditional calculation, not a measured hit rate or a promise of savings.
When would that calculation mislead you?
An archive-analysis workflow may reuse a large prefix, but the first write, cache misses, expiry and changed prefixes can add cost. The developers document different OpenAI and Anthropic caching behavior. Do not assume switching model IDs transfers a cache or enables every native cache option here.
Confirm billable categories in actual usage and account charges. Different output lengths and paid reasoning can outweigh input savings. This example stays at 100K input; it does not establish rates or accepted payloads at every context length. The dated tariff snapshot and current pricing provide the calculation inputs.
Which API IDs should your application use?
Astra uses gpt-6-astra. Fable 5.1 uses claude-fable-5.1, with a dot before the final digit. Both list OpenAI Chat Completions; Fable also lists Anthropic Messages. See the OpenAI protocol guide.
The examples below were schema-checked, not executed as paid comparisons. They show request syntax, without reproducing the benchmark harness or Max settings.
curl https://api.api-stock.com/api/v1/chat/completions -H "Authorization: Bearer $API_KEY" -H "Content-Type: application/json" -d '{"model":"gpt-6-astra","messages":[{"role":"user","content":"List the evidence needed to verify a claim in a long report."}],"max_tokens":1024}'curl https://api.api-stock.com/api/v1/chat/completions -H "Authorization: Bearer $API_KEY" -H "Content-Type: application/json" -d '{"model":"claude-fable-5.1","messages":[{"role":"user","content":"List the evidence needed to verify a claim in a long report."}],"max_tokens":1024}'
For a document trial, provide the same files and ask for a table of claims, quotations and page references. Check references against the source and count unsupported claims. For a coding trial, require passing tests. Benchmark rankings shortlist candidates; your acceptance check determines whether the result is usable. The official Astra documentation and Fable page describe native products, whose hosted tools are separate from a model response here.
FAQ
Does Astra win every benchmark?
It leads the cited coding tests and Intelligence Index; Fable leads AA-Briefcase. Agent Arena's intervals overlap, so its point estimates alone do not establish a clear winner.
Is Fable cheaper with repeated documents?
It is cheaper in the stated 95% cache-read calculation. Actual hits, writes, output usage and retries determine the bill.
Why not use the cost per task from a leaderboard?
Those figures use the operator's workloads, configurations and API tariffs. Our token-budget examples use this service's dated catalog instead.
What is the exact Fable model ID?
Use claude-fable-5.1 on this service. Both models list OpenAI compatibility; Fable additionally lists Anthropic Messages.
- llm
- benchmarks
- pricing
Try it with your own key
Choose a model in the API Stock catalog, check its price and try it in your browser or through the API.
Read next
 ComparisonGPT-6.1 Sol vs Claude Opus 5.5: benchmarks and costCompare GPT-6.1 Sol and Claude Opus 5.5 using published coding benchmarks, Agent Arena results, current API tariffs and a fixed token budget.·5 min read
 ComparisonGPT-6.1 Sol vs Claude Sonnet 5.5: benchmarks and costCompare GPT-6.1 Sol and Claude Sonnet 5.5 using Artificial Analysis benchmarks, Agent Arena intervals, API protocols and a fixed token budget.·6 min read
 ComparisonKling 4.0 vs Seedance 2.5: audio, references and costCompare Kling 4.0 and Seedance 2.5 for ten-second videos: current 720p and 1080p costs, audio, reference inputs and a realistic candidate budget.·5 min read